Build Your Own MCP Server: Give AI a New Superpower
Build a tiny MCP server from scratch: expose a useful tool, connect it to an AI host, test the conversation, and learn the safety checks that turn a fun demo into a solid integration.

On this page
Imagine your AI assistant could read a tiny “reading-time calculator” you built yourself. You ask, “How long will this article take?” and it checks the actual text instead of guessing. That little bridge between an AI app and your code is an MCP server.
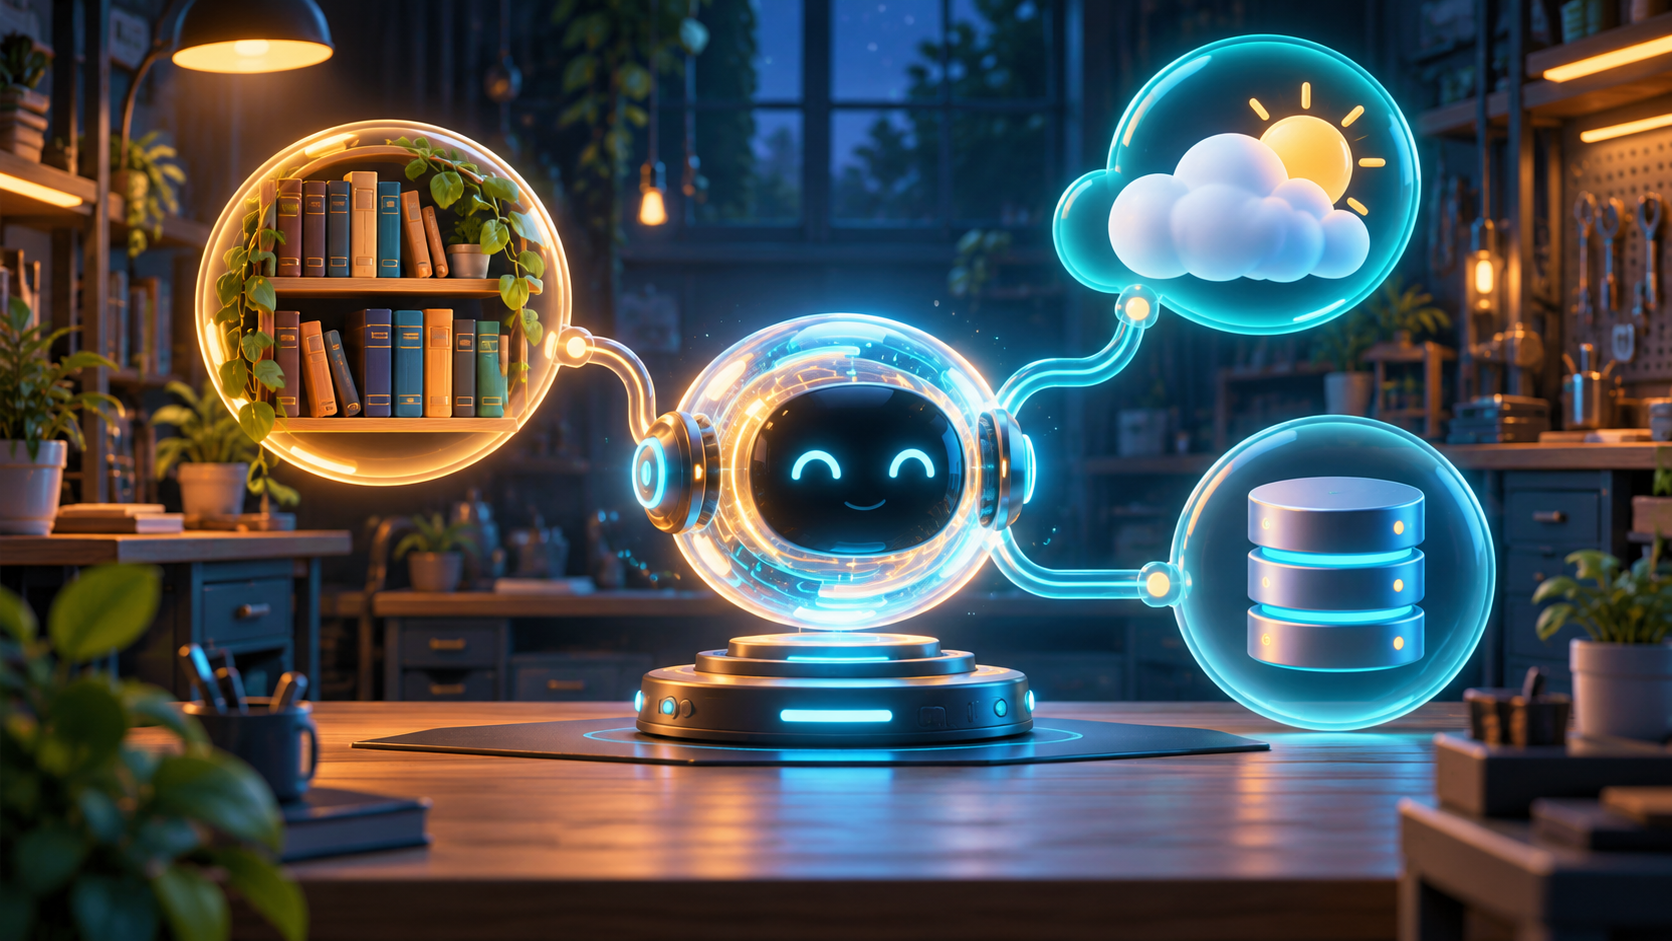
MCP (Model Context Protocol) is an open standard for connecting AI hosts to tools and data. Think of it as a well-labeled power adapter: the host speaks MCP, your server translates a useful capability into that shared language, and the model can decide when to ask for it. We’ll build a real server in TypeScript, connect it to a local host, and inspect the whole round trip.

First, a 30-second map of MCP
An MCP host is the AI application you use. Inside it, an MCP client manages a connection to each server. Your server advertises capabilities, such as tools, resources, and prompts. When the model chooses a tool, the host’s client sends a structured request to the server, which runs your code and returns a structured result.
| Capability | Think of it as | Example |
|---|---|---|
| Tool | A function the model can ask to run | Estimate how long a text takes to read |
| Resource | Data the host can fetch | A project’s README.md |
| Prompt | A reusable starter instruction | “Review this change for accessibility” |
MCP does not make the model magically reliable, and it does not itself grant access to your files or accounts. Your server’s code and the host’s permissions decide what is reachable. For our first build, we’ll expose one read-only tool with no external accounts and no secrets.
Build a tiny reading-time server
The current official TypeScript SDK is on its v2 line. Its modern stdio entry point, serveStdio, handles protocol negotiation; a server factory creates a fresh server for each connection. The SDK’s official quickstart uses Node.js 20 or newer.
Create a project and install the SDK, schema validator, and TypeScript runner:
1mkdir reading-time-mcp
2cd reading-time-mcp
3npm init -y
4npm install @modelcontextprotocol/server zod
5npm install -D typescript tsx @types/node
In package.json, add "type": "module". Then create src/index.ts:
1import { McpServer } from "@modelcontextprotocol/server";
2import { serveStdio } from "@modelcontextprotocol/server/stdio";
3import { z } from "zod";
4
5function createServer() {
6  const server = new McpServer({
7    name: "reading-time",
8    version: "1.0.0",
9  });
10
11  server.registerTool(
12    "estimate_reading_time",
13    {
14      description:
15        "Estimate how many minutes it takes to read a piece of text. Use this when someone asks for an approximate reading time.",
16      inputSchema: z.object({
17        text: z.string().min(1).max(20_000)
18          .describe("The text to estimate; maximum 20,000 characters"),
19        wordsPerMinute: z.number().int().min(100).max(1_000).default(220)
20          .describe("Reading speed; defaults to 220 words per minute"),
21      }),
22    },
23    async ({ text, wordsPerMinute }) => {
24      const wordCount = text.trim().split(/\s+/).filter(Boolean).length;
25      const minutes = Math.max(1, Math.ceil(wordCount / wordsPerMinute));
26
27      return {
28        content: [{
29          type: "text",
30          text: `${wordCount} words; about ${minutes} minute(s) at ${wordsPerMinute} words per minute.`,
31        }],
32      };
33    },
34  );
35
36  return server;
37}
38
39serveStdio(createServer, {
40  onerror: (error) => console.error("MCP server error:", error),
41});
42console.error("Reading-time MCP server ready");
That’s the whole tool. The name and description help the model decide when it fits. The Zod schema documents the inputs and rejects unsuitable ones before your handler runs. The handler does one small job and returns a text content block that the host can pass back to the model.
The limit of 20,000 characters is a basic guardrail, not a complete defense against every resource-exhaustion problem. Real services should add appropriate timeouts, quotas, and error handling too.
Test the handshake, then connect a host
Start the server from the project folder:
npx tsx src/index.tsAn MCP server over stdio waits for JSON-RPC messages on standard input and sends protocol messages on standard output. That means never use console.log() for debug output in this mode: one stray line can break the conversation. Use console.error() or a logger configured for stderr, as the example does.
You can inspect the advertised tool and make a sample call with the official Inspector. Install or invoke the current Inspector CLI according to its docs, then point it at your launch command; the MCP build guide shows the CLI workflow and how to exercise both modern and legacy protocol eras. Try text such as “MCP makes connections reusable.” The server counts four words and returns an estimate.
To attach it to a host that supports local stdio MCP servers, add an entry like this to that host’s MCP configuration (the exact file varies by host):
1{
2  "mcpServers": {
3    "reading-time": {
4      "command": "npx",
5      "args": ["tsx", "/ABSOLUTE/PATH/TO/reading-time-mcp/src/index.ts"]
6    }
7  }
8}
Use an absolute path to your project, save the configuration, and restart or reload the host. Now ask, “Estimate the reading time for: [paste a paragraph].” Watch the host list the tool, the model choose it, the client send tools/call, and your server return the result.

Follow the little round trip
1You ask a question
2        ↓
3Host sends the model the question and available tool descriptions
4        ↓
5Model chooses estimate_reading_time(text, wordsPerMinute)
6        ↓
7MCP client sends a structured tools/call request over stdio
8        ↓
9Server validates inputs → runs your handler → returns content
10        ↓
11Model explains the result in a conversational answer
The model proposes the call; the host and server execute it. That distinction matters. A well-designed tool gives the model a clear option while leaving validation and actual access control in ordinary code.
Make your server safe and useful
Small choices have a big effect on whether an MCP tool is pleasant to use:
- Write a description for a human and a model. Say what the tool does, when to use it, and what it will not do. “Estimate minutes from text; does not summarize or store it” beats “process text.”
- Validate every argument. Treat model-produced inputs like any other untrusted request. Set ranges and length limits, and return useful errors.
- Start read-only and narrow. Give a tool only the data and operations it needs. Ask for confirmation before consequential actions such as sending, deleting, purchasing, or publishing.
- Keep secrets out of prompts and logs. Use a proper secret store and narrow credentials. Avoid echoing private input in diagnostic output.
- For remote servers, secure the HTTP path. Use the current Streamable HTTP transport and implement the specification’s authorization requirements. Validate tokens for the intended audience; do not accept arbitrary forwarded tokens. Protect outbound requests against SSRF, and apply per-user limits.
- Test the boundary, not just the happy path. Try empty, oversized, malformed, and unauthorized inputs, plus upstream timeouts and failures.
The MCP security guidance calls out issues such as confused-deputy authorization bugs, token passthrough, session hijacking, and server-side request forgery. “It speaks MCP” is not a security review: least privilege, consent, and careful authorization still matter.
The fun part: make it yours
You now have a working pattern: choose one useful task, describe it clearly, define a schema, implement a small handler, and connect it over a transport. Change the calculator to estimate a recipe’s ingredient scale, summarize a local status file, or look up a public transit arrival. Add a resource when the host should retrieve data, or a prompt when you want to package a repeatable workflow.
Start with a tool that is helpful even when the AI is having an ordinary day. Then let the protocol do what a good protocol does: make your useful little capability available to more than one compatible host.
Sources and next steps
- MCP documentation: Build a server — official TypeScript setup,
serveStdio, Inspector, and host connection walkthrough. - MCP TypeScript SDK — official SDK packages and version guidance.
- MCP Security Best Practices — threats and mitigations for implementers and operators.
- MCP architecture overview — hosts, clients, servers, and transports.
Read next
A Brief History of Computer Programming: From Wires to Apps
From Ada Lovelace’s 1843 notes to today’s apps and AI coding assistants, see how programming changed—and what a program really is—in plain language.
 nbkhope
A Brief History of Programming Languages: From Machine Code to Modern Tools
From machine code and FORTRAN to Python, JavaScript, and Rust, explore how programming languages evolved and why there are so many.
nbkhope
What Is the JavaScript Programming Language? A Simple Guide to the Language of the Web
A friendly, jargon-free guide to JavaScript, the programming language that makes websites interactive. Learn what it does in your browser, how it was born in 10 days, why it gets faster as it runs, and where it's used beyond the web.
nbkhope
Comments
Be kind and specific. Comments with links from new accounts appear after a moderator reviews them.